AI Research & Codebase Intelligence
A quantitative ML research copilot that connects technical literature to source code. Hybrid retrieval and a staged LangGraph workflow support research analysis and experiment proposals with a dedicated evaluation harness.
From source documents to research decisions
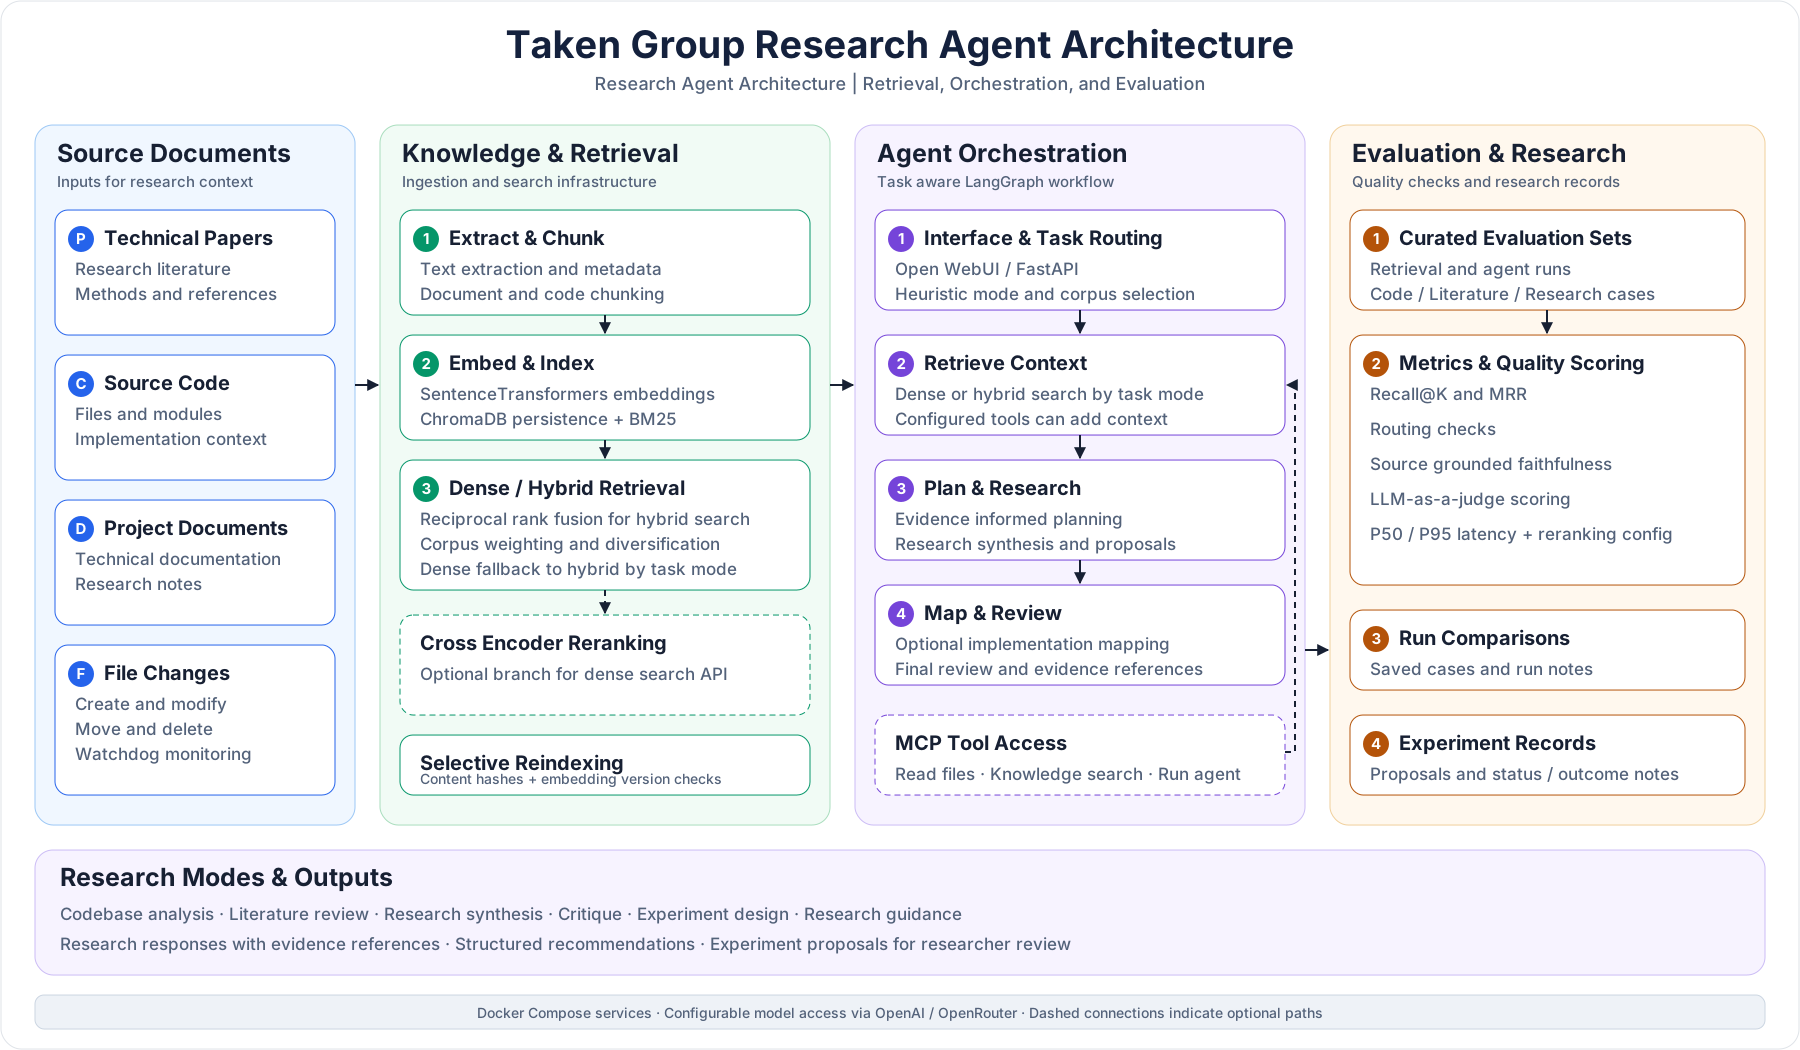
Knowledge ingestion and retrieval support the agent workflow. Evaluation runs inspect retrieval behavior and response quality separately.
Context across code and literature
Document extraction and metadata enrichment feed SentenceTransformers embeddings in ChromaDB and a BM25 index. Hybrid search combines dense and lexical rankings through reciprocal rank fusion with corpus weighting and source diversification.
A filesystem watcher tracks changes. Content hashes and embedding version checks support selective reindexing.
Optional cross encoder reranking is available through the dense search API. The core graph uses dense or hybrid retrieval.
A staged research workflow
Heuristic task routing selects a research mode and adjusts retrieval scope and corpus weights. LangGraph runs retrieval then planning and research synthesis. An optional implementation mapping stage precedes final review.
Configured MCP tools can supply context before planning. Responses request evidence references and structured recommendations or experiment proposals.
Modular services and model access
Open WebUI provides the conversational interface. FastAPI exposes agent and evaluation endpoints. Docker Compose connects the agent API with document processing and separate reranker and MCP proxy services.
OpenAI compatible inference supports configurable models through OpenAI or OpenRouter while retaining the retrieval and evaluation infrastructure.
Research quality and retrieval diagnostics
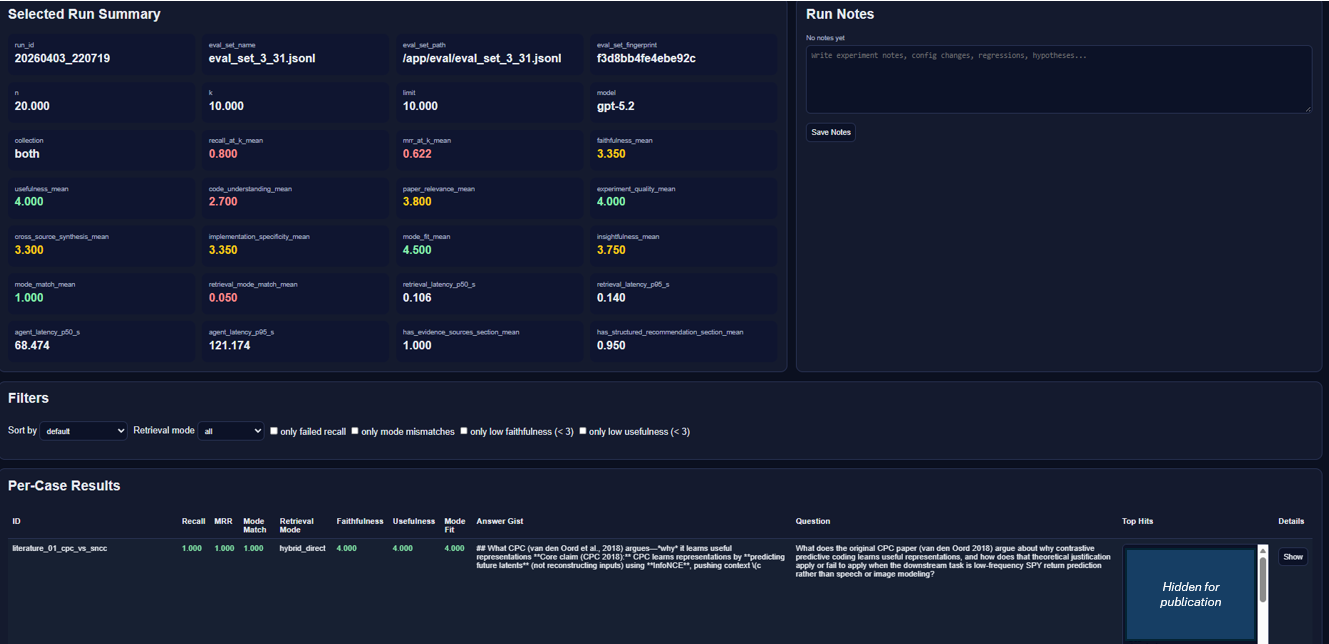
A dedicated evaluation harness runs curated test cases against retrieval and agent workflows. Metrics track retrieval relevance, response quality, research synthesis, and execution latency.
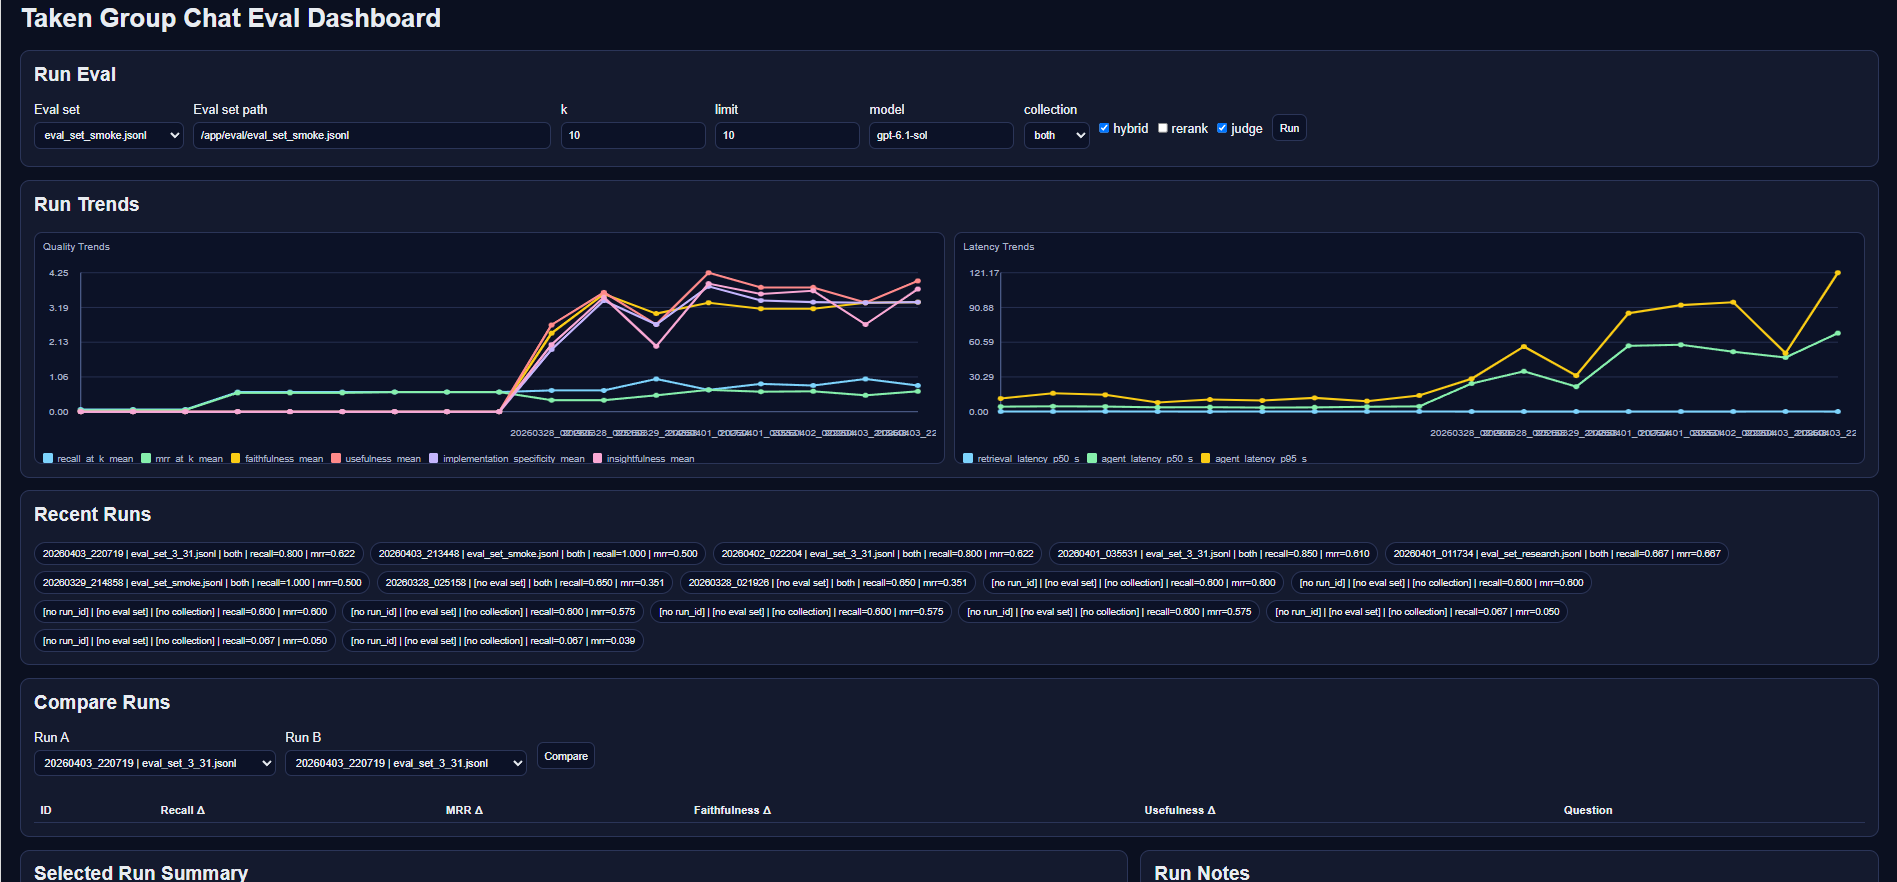
Saved evaluation runs support performance comparisons, case-level inspection, and experiment notes.
Research interface and evaluation workspace
A look inside the research agent and its dedicated evaluation framework.
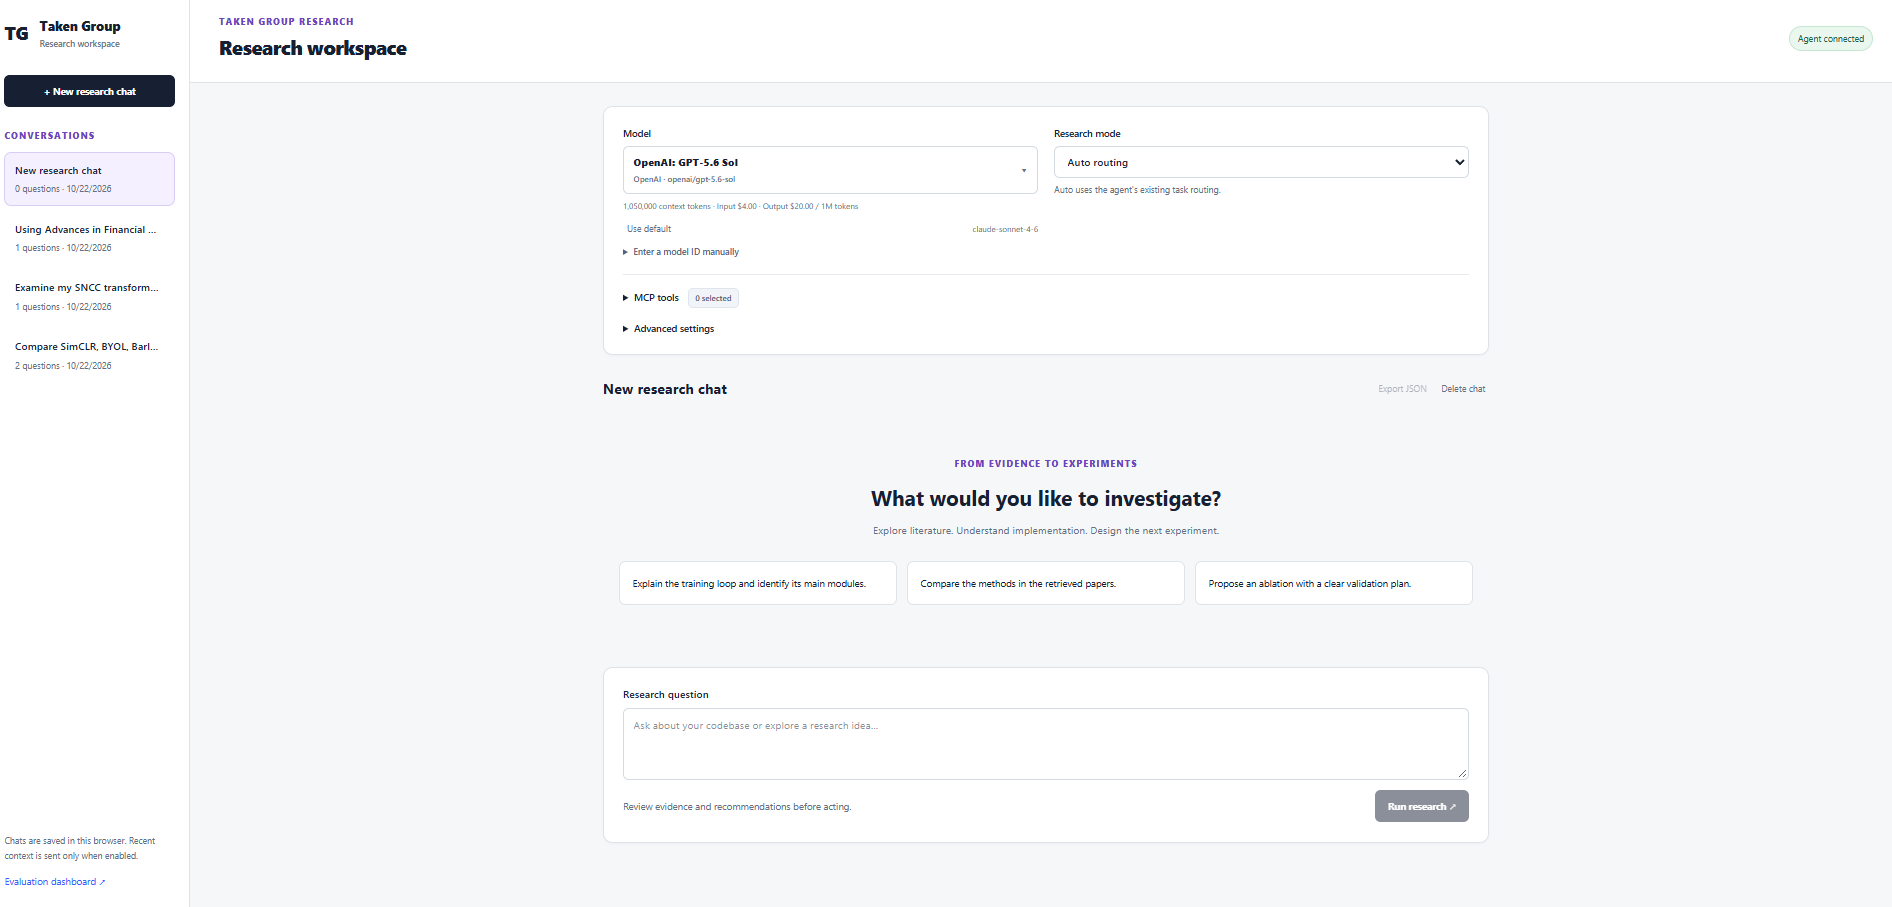
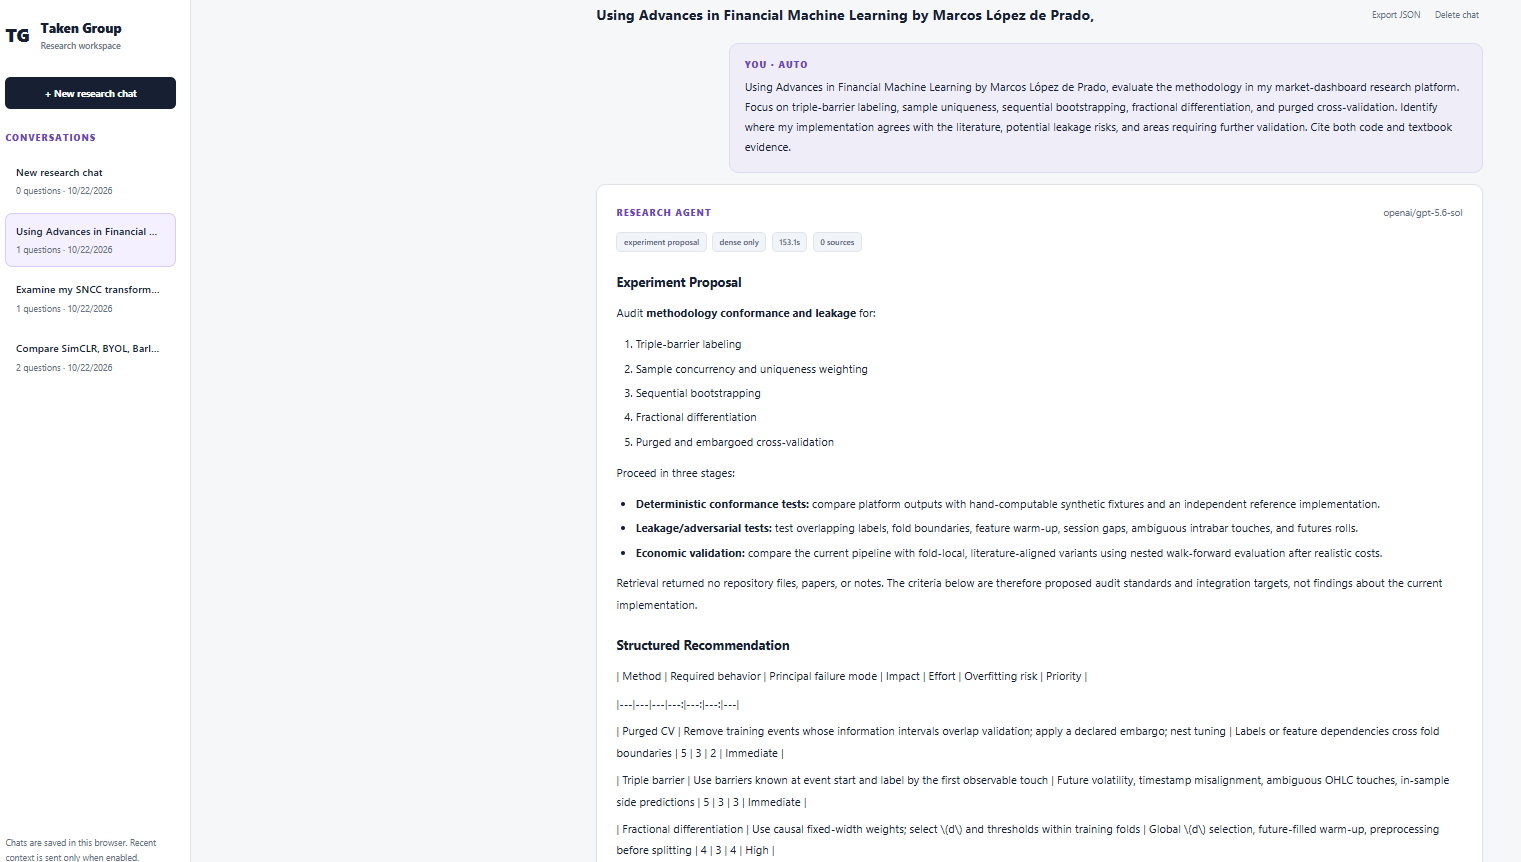
Research Agent
Interactive research workspace for technical literature and codebase analysis.
Evaluation Dashboard
Evaluation tools for analyzing retrieval and research-agent performance.
Conversation history and selected project details omitted for publication.
Architecture is simplified for public presentation. Private research materials and sensitive configuration are omitted.